I am a Ph.D. student in Computer Science at Brigham Young University (BYU), advised by Prof. Porter Jenkins and Prof. Taylor Killian, and I also collaborate with Prof. Weitong Zhang (UNC). I received my M.S. from Penn State (IST), where I was advised by Prof. Fenglong Ma (PSU), and I earned my B.S. in Mathematics from Shenzhen University.
My research focuses on LLM reasoning, particularly post-training (e.g., reasoning distillation and on-policy distillation) and test-time scaling (TTS). I am always happy to connect and discuss related ideas.
News
- 2026.10📄 New preprint CriticOPD, which recovers reliable teacher supervision in on-policy distillation via critique-guided rewriting.
- 2026.09📄 New preprint REVO, on rollout-efficient off-policy distillation via variance-guided reuse.
- 2026.09📄 New preprint An RL View of OPD, which proposes Least-Square Policy Distillation (LSPD).
- 2026.09📄 New preprint Rethinking Training–Inference Mismatch in LLM RL, which proposes calibrated importance sampling (CIS).
- 2026.09🎉 LARK was accepted to NeurIPS 2026.
- 2026.09🔥 New preprint When EOS Tokens Disagree, on length inflation in on-policy distillation, ranked #3 Paper of the Day on 🤗 Hugging Face.
- 2026.08🎉 Self-Correction Can Amplify Hallucinations was accepted to EMNLP 2026.
- 2026.01🎉 ICPO was accepted to ICLR 2026.
Publications
Recent work on LLM reasoning. See Google Scholar for the full list.
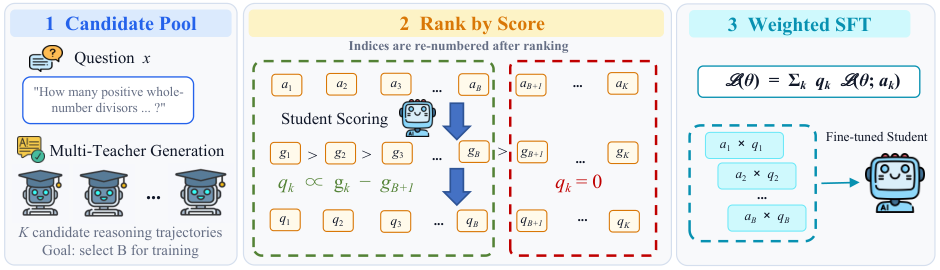
LARK: Learnability-Grounded Trajectory Selection for Efficient Reasoning Distillation
Tianrun Yu, Kaixiang Zhao, Chih-Chun Chen, Amanda Hughes, Taylor W Killian, Fenglong Ma, Weitong Zhang, Porter Jenkins
- Selects teacher reasoning trajectories by how efficiently the student can learn them, with a χ²-regularized selection policy that preserves distributional coverage.
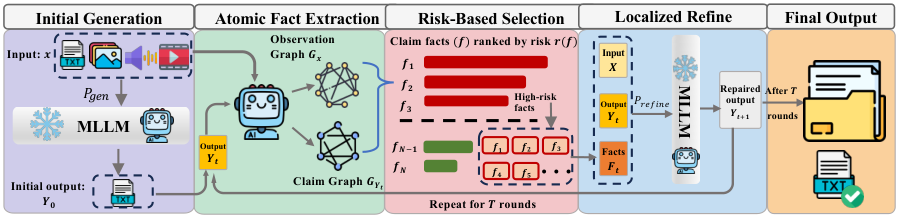
Kaixiang Zhao, Tianrun Yu, Shawn Huang, Porter Jenkins, Yushun Dong, Amanda Hughes
- Shows that jointly conditioned self-correction can amplify hallucinations, and repairs high-risk facts via independently extracted observation and claim graphs.
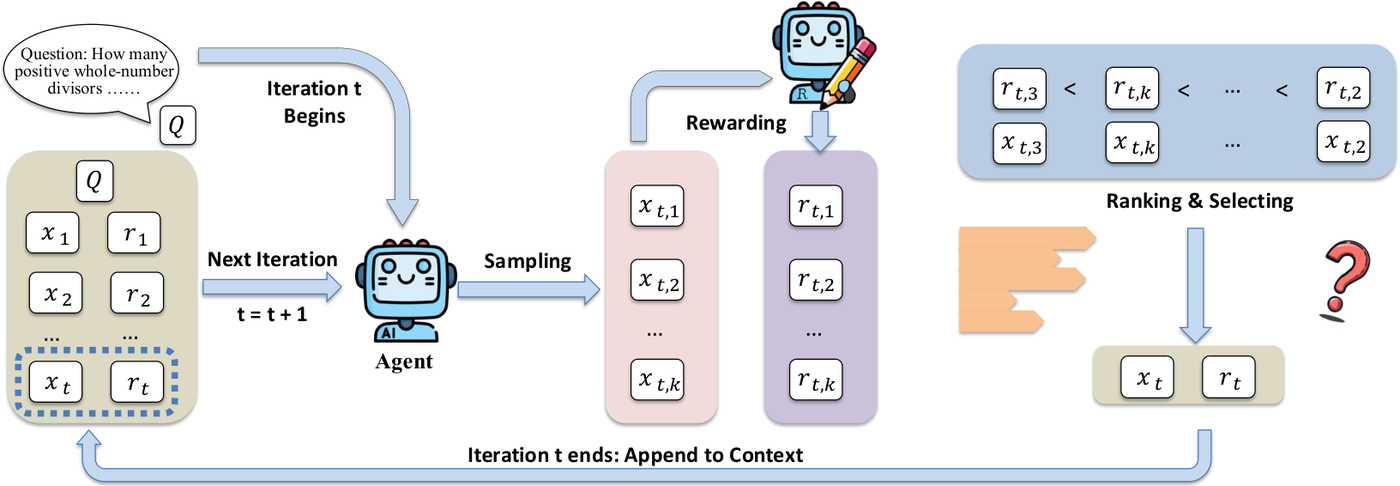
Provable and Practical In-Context Policy Optimization for Self-Improvement
Tianrun Yu, Yuxiao Yang, Zhaoyang Wang, Kaixiang Zhao, Porter Jenkins, Xuchao Zhang, Chetan Bansal, Huaxiu Yao, Weitong Zhang
- Explains multi-round self-reflection as in-context policy optimization with provable guarantees, and proposes ME-ICPO for affordable test-time scaling on math reasoning.
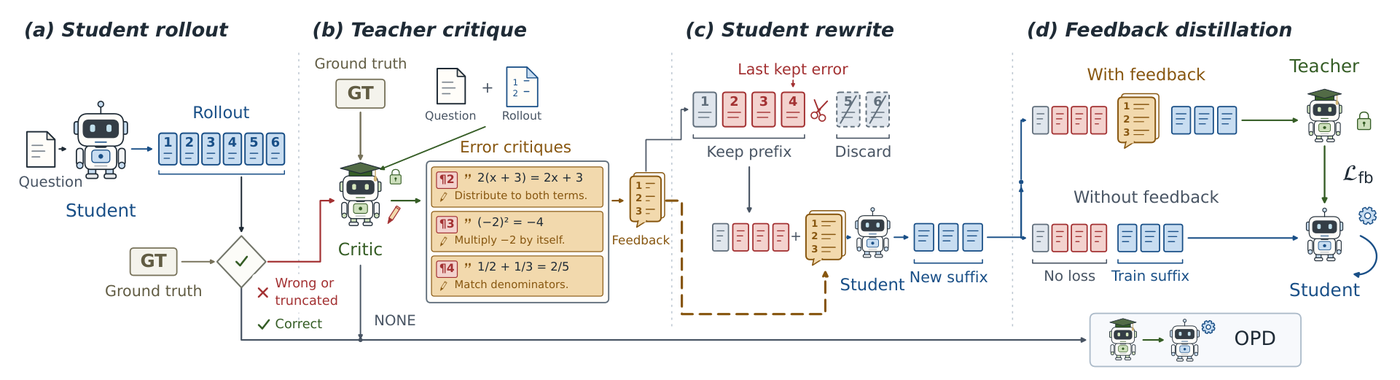
Recovering Reliable Supervision via Critique-Guided On-Policy Distillation
Kaixiang Zhao, Tianrun Yu, Shangzhe Li, Yuxiao Yang, Amanda Hughes, Weitong Zhang, Taylor W Killian
- Shows that the OPD teacher often follows student errors even though it recognizes them, and restores reliable supervision (CriticOPD) by having the teacher critique incorrect rollouts and the student rewrite from the last error.
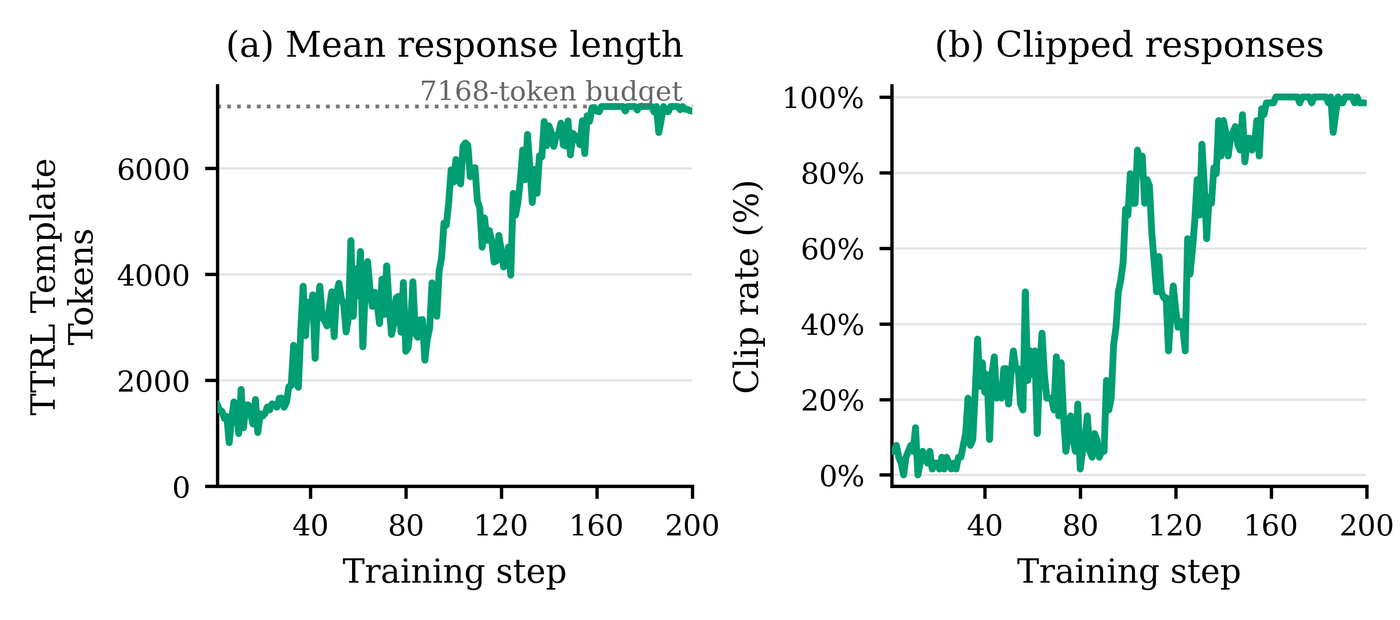
When EOS Tokens Disagree: Understanding Length Inflation in On-Policy Distillation
Yuxiao Yang, Tianrun Yu, Shangzhe Li, Kaixiang Zhao, Xuchao Zhang, Chetan Bansal, Huaxiu Yao, Taylor W Killian, Weitong Zhang
arXiv 2026 arXiv PDF Website 🤗 #3 Paper of the Day
- Identifies termination-token mismatch between student and teacher as a key source of length inflation in on-policy distillation, and mitigates it by treating equivalent EOS tokens as a shared stopping action.
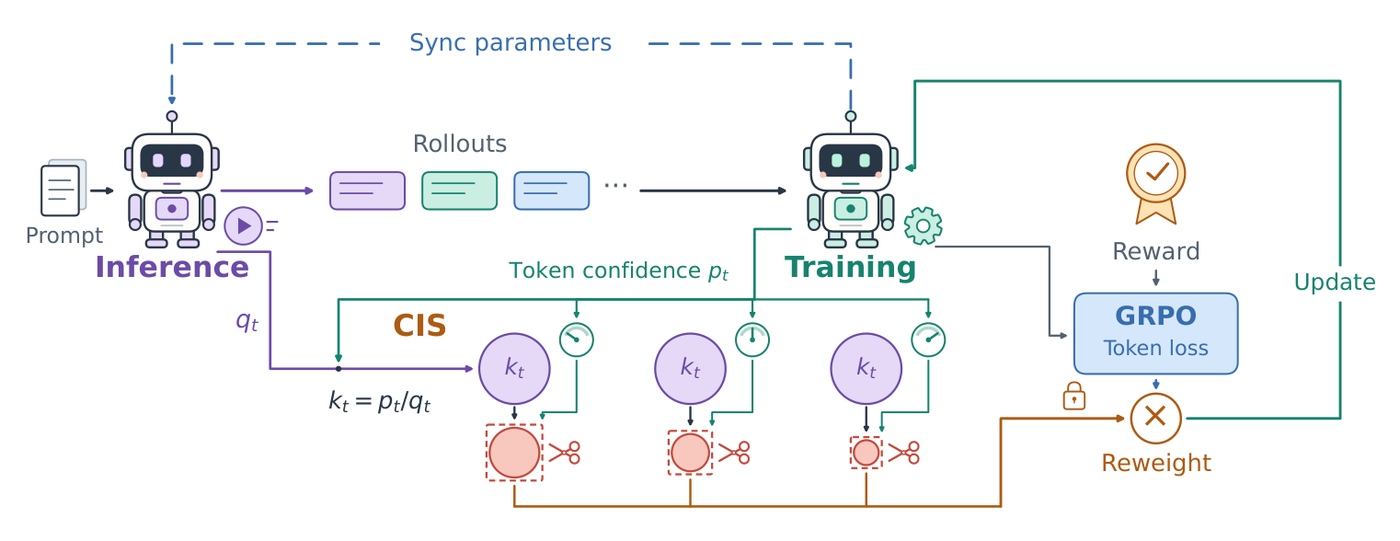
Tianrun Yu, Kaixiang Zhao, Shangzhe Li, Yuxiao Yang, Porter Jenkins, Weitong Zhang, Taylor W Killian
- Characterizes the training–inference mismatch in RLVR as an additive log-odds displacement, and proposes calibrated importance sampling (CIS), a confidence-aware truncation with a bounded second moment.
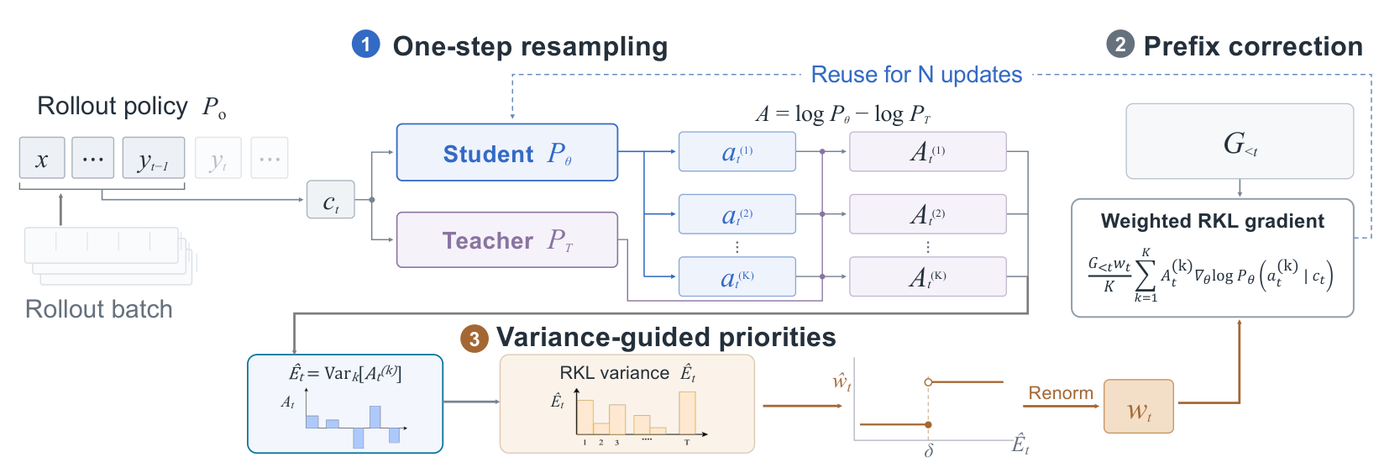
REVO: Rollout-Efficient Off-Policy Distillation via Variance-Guided Reuse
Yuxiao Yang, Shangzhe Li, Tianrun Yu, Kaixiang Zhao, Taylor W Killian, Weitong Zhang
- Reuses each student rollout for multiple updates via one-step resampling, stabilized prefix weighting, and variance-guided token priorities; 50 rollout iterations match or exceed OPD trained for 200.
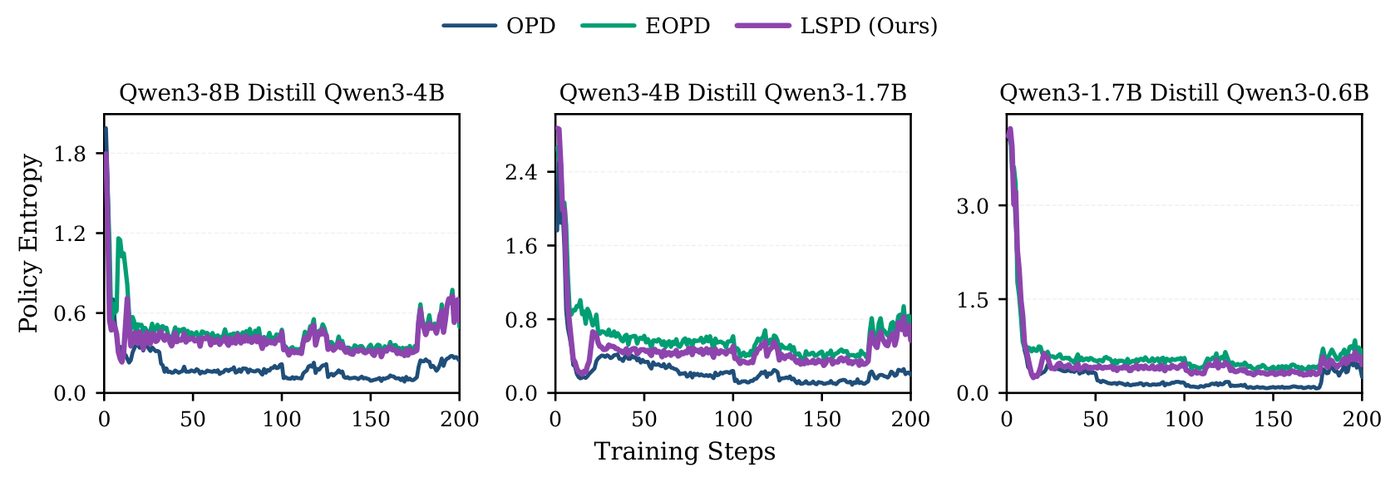
An RL View of OPD: Least Square Policy Distillation for Sample-Efficient LLM Reasoning
Shangzhe Li, Yuxiao Yang, Tianrun Yu, Kaixiang Zhao, Xiaoyun Wang, Taylor W Killian, Weitong Zhang
- Connects reverse-KL OPD to KL-regularized policy optimization, and brings optimistic exploration and off-policy data reuse into distillation to preserve policy diversity.
Education
Ph.D. in Computer Science
M.S. in Informatics
B.S. in Mathematics